- Text
- Voice
- Image
- Video
Unified Multimodal Input
Text, voice, images and video accepted together in one conversation, understood as a single request.
AI Agent Development / Multimodal Agents
Multimodal AI agents for US businesses. They understand text, voice, images and video together, and reply in the format that fits, from speech to annotated images.
"Pump 3 is leaking near the valve, what do I do?"
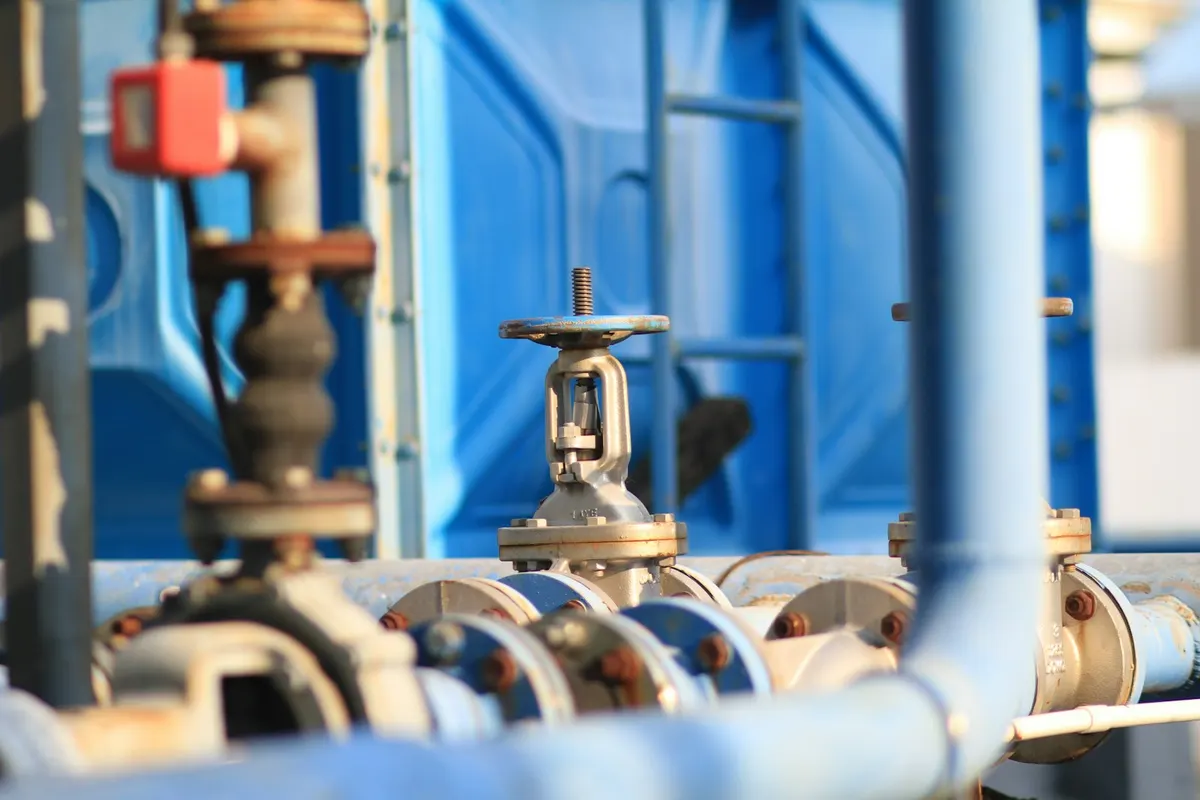 IMG_2231.jpgworn gasket · 0.93
Real work involves photos, calls, screens and documents. Multimodal agents handle all of them in one flow.
Text, voice, images and video accepted together in one conversation, understood as a single request.
Vision-capable models such as GPT-4o and Claude, or specialised CV models, to read, inspect and describe what's in front of them.
Speech-to-text, natural text-to-speech and low-latency voice conversations, with tone and sentiment awareness.
The agent picks how to answer, text, table, chart, annotated image or audio, based on the task and the user.
Memory that links what was said, shown and written, so the agent can refer back to an earlier photo or call.
Does your work happen in photos, calls and video?
Let's build an agent that understands all of it.
Examples of multimodal agents we build, combining two or more inputs into one useful result.
Insurance
Manufacturing
Healthcare
Retail
Real Estate
Customer Service
Context doesn't reset when the format changes. A question on a call can be answered with a photo from two days ago.
Mon 09:12
Uploads a photo of a cracked tile in unit 4B
Mon 09:12
Logged: hairline crack, bathroom floor, ~12 cm. Ticket #3381 opened.
Wed 16:40
Voice call: "Is that the same crack the plumber looked at?"
Wed 16:40
Yes, it's the crack from Monday's photo. The plumber found no leak underneath; a tiler is booked for Friday.
Linked: Monday photo + ticket #3381 + plumber's note
Teams share what changed once their agents could see, hear and speak.
Claims from a few photos
Customers snap the damage, describe it out loud, and the estimate is ready in minutes.
Experienced healthcare software developers and teams working across a wide range of technologies and frameworks.


Our healthcare engineers are happy to talk specifics.
An agent that understands and produces more than text: it can work with voice, images, video and documents together, and choose the best format for its reply.
Vision-capable models such as GPT-4o, Claude and Gemini, specialised computer vision models where accuracy matters, and speech services such as Whisper, Deepgram and ElevenLabs for voice.
Yes. We build low-latency voice agents with streaming speech recognition and natural text-to-speech, including interruptions and handoff to a person.
Yes. Video is sampled into frames and audio, analysed together, and summarised or searched, for example to find a moment or list defects in a walkthrough.
Media is encrypted, stored only as long as your retention rules allow, faces and personal data can be blurred or redacted, and processing can run in your own cloud.
Yes. Agents connect to your CRM, ticketing, ERP, EHR or claims systems so what they see and hear turns into real records and actions.
It depends on the task. We test on your own images, add specialised models where general ones fall short, and route low-confidence cases to a person.
A focused multimodal agent usually takes 6–10 weeks, depending on modalities, integrations and how much custom vision work is needed.
Multimodal AI agents that understand text, voice, images and video, and answer in the right format.